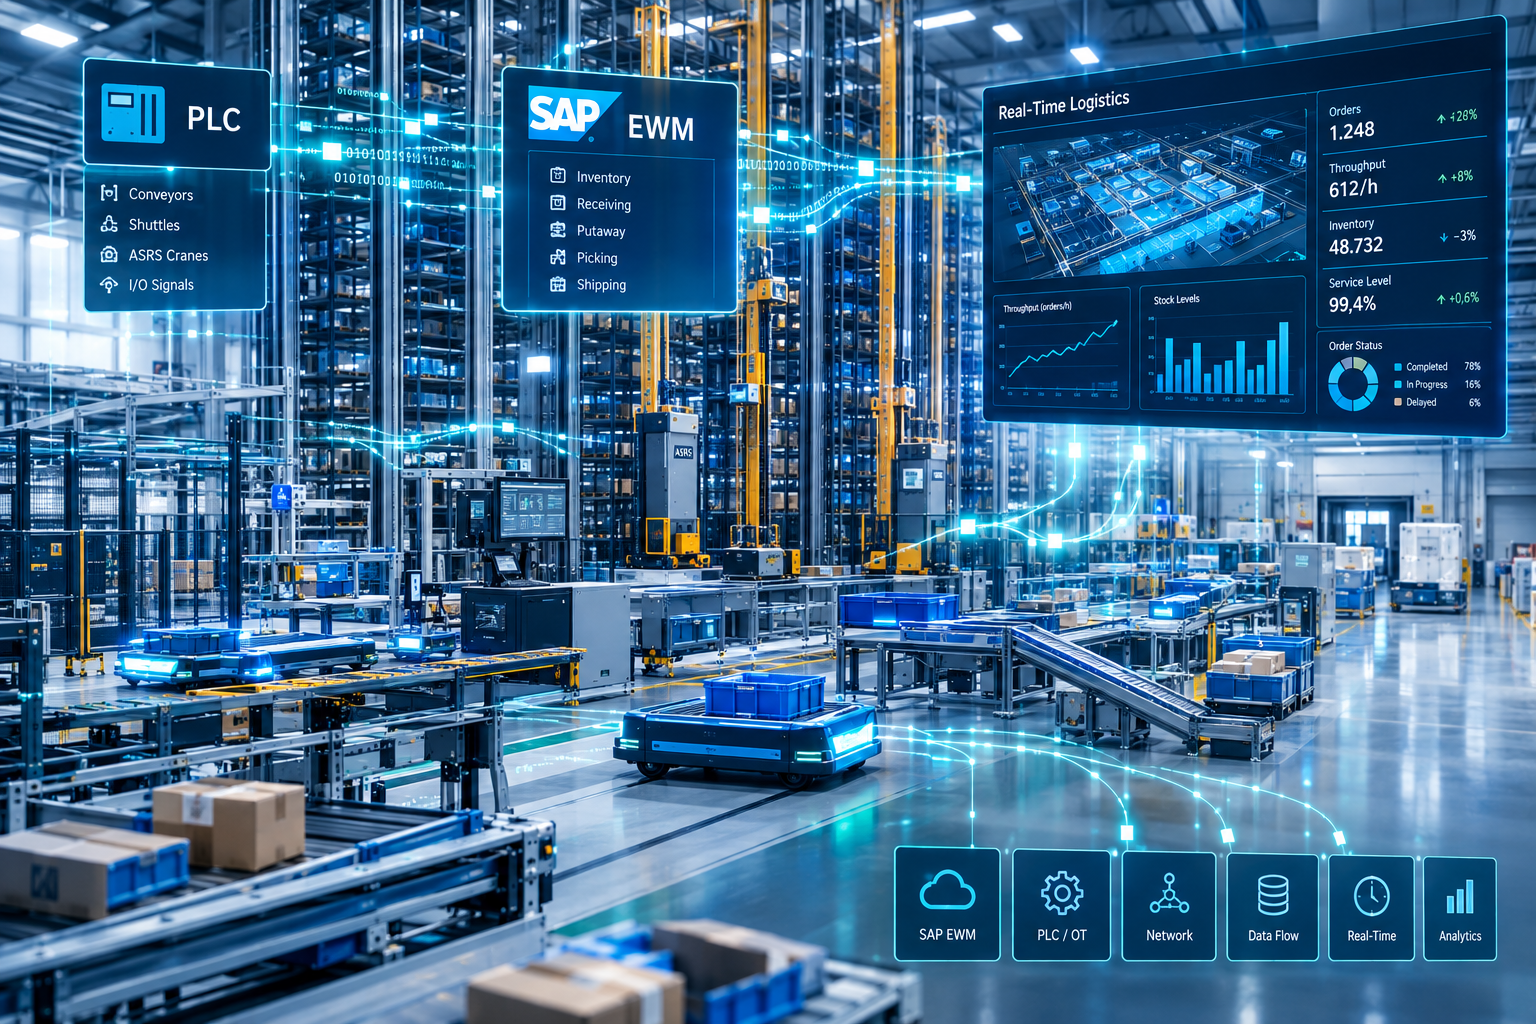
Key Takeaways at a Glance
Telegram communication is the operational clock between SAP EWM and the underlying control system. When the material flow stalls, the cause often lies in the communication path rather than in the business logic. Telegram monitoring makes these causes visible and failure patterns reproducible.

Channel “up” does not mean “synchronized”
For stable processing, channels must be synchronized and telegrams must be acknowledged by the PLC before EWM books them as sent.
Retries explain many “duplicate” telegrams
Repetitions are standard behavior when an acknowledgment is missing; a high retry share is an early indicator of problems.
A telegram backlog is usually a queue issue
Missing acknowledgments, overly coarse serialization and a lack of parallelism make queues and buffers grow and throughput drop.
Why “Telegram Monitoring” Decides Stability in MFS Projects
In SAP EWM MFS, telegram communication is not an “interface detail” but the operational clock between SAP and the underlying control system (PLC). When the material flow stalls, HU positions “jump” or throughput collapses, the cause in practice is very often not the business logic (e.g., putaway strategy) but a fault in channel state, handshake, retry, queue serialization or telegram processing.
Telegram monitoring is therefore not a purely IT discipline but part of operational readiness: it links technical signals (timeouts, buffers, channel synchronization) with business objects (WT/WO/HU) and makes failure patterns reproducible – the prerequisite for reliable debugging and stable hypercare.
For an overview of where material flow control sits in the automation stack, see our service page SAP EWM Material Flow Control.
Structure of Telegram Communication: From the TCP/IP Stream to MFS Processing
Transport: TCP/IP, Socket/Stream and the “Communication Channel”
SAP EWM MFS communicates with a PLC via TCP/IP and uses communication channels (“channels”) that are described by host/IP and port. What matters: in this context, TCP/IP is typically stream-oriented – there are no guaranteed message boundaries. This is exactly why mechanisms such as fixed telegram lengths, delimiters or header length fields are so important in practice.
Protocol Level: Data Telegram vs. Acknowledgment (Handshake)
At protocol level, MFS distinguishes between data telegrams (carrying payload data that is to be processed) and acknowledgment telegrams (acknowledgment or acceptance/rejection response at protocol level). This distinction is central to retry mechanisms and to diagnosing “lost” vs. “duplicate”.
Processing in SAP: Receipt, Parsing, Mapping, Follow-Up Actions
For the receipt and processing of incoming telegrams, SAP EWM MFS uses standard logic (e.g., via a receiving function module) that puts the channel/PLC into context, formats telegrams and transfers the content into an overall structure from which the telegram type/structure is then derived and processed. If the header or structure cannot be determined unambiguously, error cases arise that typically do not show up as a “wrong business process” but as a processing error in the communication path.
Telegram Types: Which Classes You Need to Distinguish in Monitoring
In real projects, the specific telegram families vary (OEM/subsystem-specific). For monitoring and debugging, however, a robust classification by functional effect is essential:
Movement/Transport Order
EWM → PLCTelegrams that trigger a physical transport order (typically: “move”, “drive”, “route to CP”).
Arrival/Acknowledgment
PLC → EWMTelegrams that report that an HU has arrived at a reporting point/CP; this often results in the confirmation of a WT/LB and the triggering of the next process step (e.g., routing/LOSC follow-up step).
Status/State Telegrams
bidirectionalQueries or messages about the state of communication points, resources or segments (e.g., “blocked”, “available”, “fault”).
Life/Heartbeat Telegrams
Telegrams for channel checks during communication silence or for vitality checks.
Error/Exception Telegrams
PLC → EWMTelegrams that carry PLC error codes and are mapped in EWM to exception handling and follow-up actions.
PLC Communication & CP Channels: What “Synchronization” Really Means
A common misconception in operations is: “The channel is up, so communication is running.” In MFS, the channel state is only one part. For stable processing, channels must be synchronized. In this context, synchronization means: after the connection is established, the PLC was able to send all messages that accumulated during the disconnection; the PLC send buffer is empty, and every telegram sent is acknowledged by the PLC before EWM books it as sent.
Operationally relevant:
- As long as the channel is synchronized, EWM sends telegrams automatically.
- If the acknowledgment is missing, the repeat mechanism (retry) kicks in.
- If no communication takes place at all, EWM starts a channel check via life telegram (interval configurable).
When the material flow stalls, the cause rarely lies in the business logic.
Very often the fault lies in channel state, handshake, retry, queue serialization or telegram processing. Telegram monitoring links technical signals such as timeouts, buffers and channel synchronization with business objects (WT/WO/HU) and makes failure patterns reproducible.

Queue Processing: Why a Telegram Backlog Is Almost Always a Queue/Serialization Problem
Queue Determination and Serialization
MFS uses queues to serialize processing and to control responsibility (e.g., for resources/plant areas). The queue logic directly influences whether telegrams are created and processed in the expected sequence and whether parallelism is used effectively.
KZSUB/“Send Status” as a Diagnostic Lever
In operational monitoring, a key signal is whether a WT is “subsystem-relevant” and whether it has already been sent to the subsystem or can be sent. This status logic is typically visible in MFS operating views and is also used in projects to enable a targeted resend.
Typical Causes of Queue Backlogs
- Downstream blockage: PLC/plant does not acknowledge or acknowledges slowly ⇒ queue grows.
- Lack of parallelism: queue cuts that are too coarse, everything in one serialization.
- Race/out-of-order: competing flows that are logically separate but technically serialized together. (Diagnostically visible via telegram sequence and buffer growth).
Retry Mechanisms: How to Cleanly Separate “Lost” from “Duplicate”
EWM automatically repeats unconfirmed telegrams after an interval that can be configured on the channel.
This is technically correct – but leads to typical misunderstandings:
- “Duplicate telegrams” are often retries because an ACK arrived late.
- A robust system must handle retries idempotently (the acknowledgment logic must recognize: “I already know this one”).
- A high retry share is an early indicator of problems in channel quality, PLC load or processing time in SAP.
Monitoring Transactions & Operational View: What Really Matters in the Control Room
Central Hub: Warehouse Monitor
In MFS operations, the Warehouse Monitor is typically used as the central view. The following monitoring objects, among others, are relevant there:
- Status of the communication channels
- Status/configuration of the communication points
- Telegram Log
- Overview of HUs on the conveyor system
- Open MFS-relevant warehouse tasks
- Resource status (e.g., SRMs)
- Incoming/Outgoing Telegram Buffer
Operational MFS Maintenance/Analysis Transactions
For support/hypercare, in addition to monitoring you also need maintenance/analysis access to MFS objects (e.g., communication points, PLC objects, channels, resources, object mapping, log cleanup). In real projects, this is covered through dedicated roles and MFS transactions.
Logging: What You Need to Log (and How to Make Logs “Shift-Ready”)
A telegram log is only operationally valuable if it makes the leap from “raw data” to “diagnosable information”. In practice, the following works well:
- Context fields (e.g., area, plant/subsystem ID, CP groups) in the log view
- Structured field rendering per telegram type (not every line is the same)
- Color highlighting of relevant fields per type
- “Telegram Content View” detail view for quick interpretation in the control room
The goal is clear: a shift supervisor must be able to see within seconds who sent, what was sent, whether it was acknowledged, which object is affected and where the process is stuck.
Performance Aspects: Latency Is Not a Nice-to-Have but Material Flow
In the MFS environment, performance problems show up very directly as:
- delayed telegram processing
- rising queue lengths
- growing buffers
- falling throughput because the plant is “waiting for SAP”
Typical technical causes are:
- insufficient parallelism in telegram processing
- slow action processing logic
- unfavorable MFS process settings/mapping
Consequence for monitoring: you need not only “error monitoring” but also KPI monitoring (telegram response, retry rate, buffer trend, queue trend).
Typical Failure Patterns: Symptoms → Causes → Debugging Approach
Lost Telegrams
- Symptoms
WT stays open; HU is standing still physically; no progress; buffer/retry rising.
- Causes
missing ACK, connection interruption, parsing/structure errors.
- Debugging
Channel synchronized? ACK path visible? Telegram type/structure recognized correctly?
- Symptoms
Duplicate Telegrams
- Symptoms
PLC reports “already done”; EWM shows repeated transmissions; states become inconsistent.
- Causes
Retry + late ACK; missing idempotency.
- Debugging
Retry interval/ACK timing; unambiguous assignment via handshake differentiation.
- Symptoms
Timeouts
- Symptoms
sporadic retry bursts; latency peaks; sporadic backlogs.
- Causes
PLC load, SAP processing time, channel quality.
- Debugging
Buffer trend + telegram response times + retry rate.
- Symptoms
Telegram Backlog
- Symptoms
Outgoing/incoming buffer grows; queue hangs; throughput drops.
- Causes
Serialization/queue design; lack of parallelism; missing acknowledgments.
- Debugging
Where does the backlog begin (CP/queue/channel)? Which telegram class is affected?
- Symptoms
Asynchronous States (Physical ≠ Logical)
- Symptoms
HU position in SAP deviates; follow-up processes run into the void.
- Causes
missing/late arrival telegrams; exception handling mapped incorrectly; follow-up actions do not take effect.
- Debugging
Trace the telegram chain (registration → transport order → completion); check the exception chain.
- Symptoms
Go-Live Support & Hypercare: Operational Monitoring as a Setup of Its Own
For MFS go-lives, the following applies: stability does not come from “more people” but from clear operating tools:
- preconfigured monitor views (per area/plant)
- defined alarm/threshold values (retry rate, buffer growth, channel synchronization)
- runbooks: “If X, then check Y”
- clear escalation logic between the SAP team and the PLC team
Hypercare is efficient when the most important debugging questions can be answered within minutes:
- Is it the channel?
- Is it the ACK/retry?
- Is it the queue/serialization?
- Is it an MFS action/exception sequence?
Debugging Playbook
Diagnostic Path
ChannelHandshakeBufferQueueAction/ExceptionReproducibilityStep 1 – Channel & Synchronization
Is the channel synchronized, are life checks taking place, are retries running?
Step 2 – Telegram Type & Handshake
Is it a data telegram or an acknowledgment? Is an ACK generated/received?
Step 3 – Buffer Trend
Is the incoming/outgoing buffer growing? Then it is rarely “business”, but rather processing/ACK/serialization.
Step 4 – Queue Situation
Which queue is blocking? Is the serialization sensible or too coarse?
Step 5 – Follow-Up Actions / Exception Handling
Which action is triggered by the telegram? Are PLC error codes mapped correctly to EWM exceptions and are follow-up actions executed?
Step 6 – Reproducibility
Can the failure pattern be reproduced using defined telegram sequences (test/simulation)? This is the key to sustainable fix quality.
To learn how we support telegram processing and reproducible simulation-based tests in SAP EWM MFS, see the page Qinlox Toolbox for SAP EWM MFS.
Conclusion: Telegram Monitoring Makes Stability Measurable
When SAP EWM MFS controls highly automated facilities, telegram monitoring is the key tool for making stability measurable – and for not just “solving” failure patterns but systematically preventing them.
Frequently Asked Questions About Telegram Monitoring in SAP EWM MFS
Would you like to learn more about telegram communication and fault diagnosis in SAP EWM MFS? Below you will find answers to common questions on acknowledgment, retries, queues, logging and hypercare.
If no acknowledgment arrives and retries keep running, that is a strong indication. What matters is the view of handshake/ACK and channel synchronization.
Retries are standard behavior when an acknowledgment is missing. Without clean idempotency, this looks like “duplicates”.
After the connection is established, the PLC was able to send pending messages; the PLC send buffer is empty and ACK processing works.
If no telegram communication takes place, EWM checks the channel via life telegrams (interval configurable).
Typically due to missing ACKs, overly coarse serialization or a lack of parallelism in processing/queues.
Queues control serialization and sequence; wrong queue cuts cause backlogs and unwanted blockages.
PLC error codes are transmitted in telegrams and mapped to exception codes in EWM, which trigger follow-up actions.
Because logs without context fields and structured presentation per telegram type take too long to interpret. Structured views therefore make sense.
Through rising latencies, growing buffers/queues and falling throughput – often coupled with processing or parallelism problems.
Preconfigured monitoring views + KPI thresholds + a debugging runbook along channel/ACK/buffer/queue/exception.